🔍 Read the full analysis: Follow A Handwritten 7 Through The Layers Of A Neural Network on ThorstenMeyerAI.com

Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
A November 8, 2026, explainer from ThorstenMeyerAI.com traces how a feedforward neural network turns 784 pixel values into a handwritten-digit prediction. It illustrates the arithmetic with a nine-parameter XOR network, then describes a digit reader with 109,386 parameters; the source also reports a separate AI weight-editing result that has not been peer reviewed.
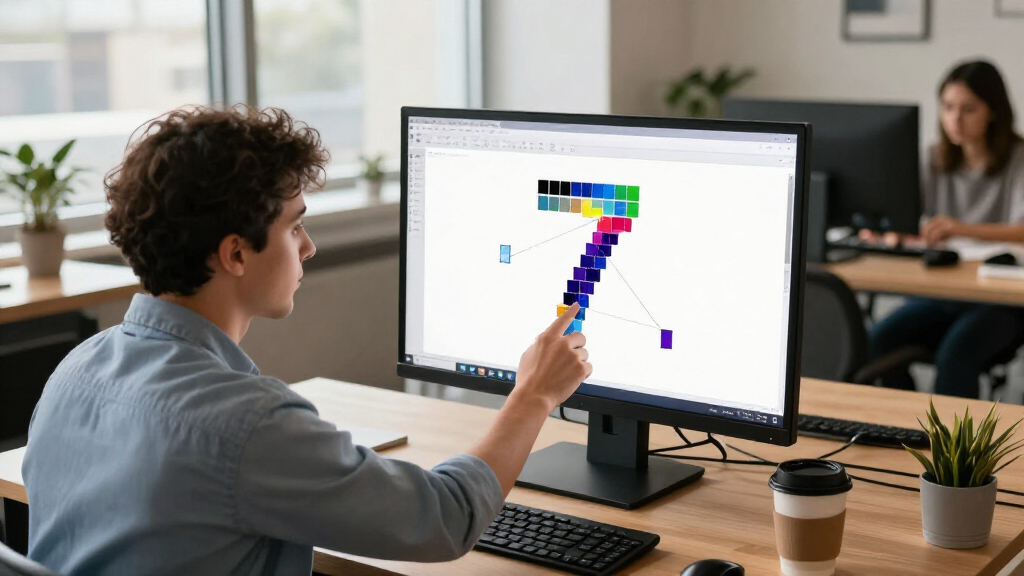
ThorstenMeyerAI.com published an explainer on November 8 showing how a feedforward neural network can classify a handwritten seven by passing pixel values through layers of arithmetic. The article uses a deliberately small XOR network to show how changing one bias can alter a function, before describing a digit-reading network with 109,386 parameters.
For the digit example, a 28-by-28 image is flattened into 784 pixel values. The input layer holds and passes those values; it does not transform them. For more on how AI can alter a network’s parameters, see AI that edits neural networks through their weights. In a dense layer, each neuron multiplies inputs by weights, adds a bias and applies an activation function. The resulting values become inputs to the next layer. An output layer can produce ten scores, one for each digit, with the highest score used as the prediction.
The explainer demonstrates the process with XOR, a function that returns one when two input bits differ and zero when they match. Its hand-built network has two hidden neurons and one output neuron, with a step activation. The article lists nine weights and biases for the network and works through how the hidden neurons’ outputs feed the final calculation, illustrating the role of weights and biases.
Changing the output neuron’s bias from −2 to −1 makes the example return one for every input, rather than only when the bits differ. The network’s other values and structure stay the same. The article says a larger digit reader contains 109,386 parameters, with about 92% in its first layer, where each pixel connects to each of 128 units.
Infographic 01 · One bias, two behaviors
A network you can run by hand
Two hidden neurons check "at least one bit is on" and "at most one bit is on". The output neuron needs both. Change its bias and it needs only one.
Move the output bias from −2 to −1 and the network stops computing XOR: it returns 1 for all four inputs.
The whole network
Hidden 1: step( x₁ + x₂ − 1 )
Hidden 2: step(−x₁ − x₂ + 1 )
Output:   step( h₁ + h₂ − 2 )
step: 1 if the total is zero or greater, otherwise 0. Nine numbers in total: six in the hidden layer, three in the output neuron.
All four inputs
Hidden outputs and the final output with the original and the changed bias
| Input | At least one | At most one | Output, bias −2 | Output, bias −1 |
|---|---|---|---|---|
| 0, 0 | 0 | 1 | 0 | 1 |
| 0, 1 | 1 | 1 | 1 | 1 |
| 1, 0 | 1 | 1 | 1 | 1 |
| 1, 1 | 1 | 0 | 0 | 1 |
Sources: own arithmetic, checked with a script · the XOR example as in Goodfellow, Bengio, Courville: Deep Learning, ch. 6.
Powered by Thorsten Meyer AI
Why One Bias Can Change the Output
The examples make the mechanics of a neural network less opaque: an output follows from values passed through layers, not from a hand-written rule describing what a seven looks like. In the XOR demonstration, a single number changes the network’s behavior across all four possible inputs. That small case is easy to inspect and calculate directly.
The same simplicity does not carry over to a trained digit reader. Its 109,386 parameters can interact across layers, and the explainer says a behavior in such a network may depend on patterns spread across many weights rather than one isolated bias. The contrast helps readers understand why directly changing a model’s weights is a different task from editing the small example.
The source also connects that distinction to a reported MIT CSAIL experiment in which an AI model read and edited another network’s weights. It says one edit altered 0.016% of a language model’s weights and raised a math score from 7.9% to 48.1%. Those figures are claims reported by the source, not independent findings established by the explainer; the source describes the underlying material as a blog post with public logs, not a peer-reviewed paper.
Products Worth Considering
Logitech MX Creative Console with 9 Customizable Keys, Graphite

LG 34WR55QK-B 34-inch Curved UltraWide WQHD Monitor

Samsung 34-inch ViewFinity S50GC Ultra-WQHD Monitor
As an affiliate, we earn on qualifying purchases.
From Pixel Inputs to Learned Weights
The article focuses on a multilayer perceptron, a feedforward network made of dense layers. It distinguishes three roles: the input layer holds the data, hidden layers calculate intermediate values, and the output layer supplies the result. “Hidden,” in this account, means intermediate—not inaccessible. Each layer’s operations can be written as z = W x + b, followed by an activation function; the symbols represent the inputs, weights and biases.
The XOR network is constructed by setting its values to match a desired behavior. That differs from ordinary training, where a model’s weights and biases are learned from data. The source also distinguishes architecture choices from learned values: width and depth describe the number of units and layers, while weights and biases are parameters. It notes that early image-network layers have been found to respond to simple patterns such as edges, with later layers responding to object parts; this is background, not a finding specific to the seven demonstration.
“A neural network is arithmetic in layers.”
— Thorsten Meyer, ThorstenMeyerAI.com
Limits of the Reported Weight Edit
The explainer does not identify the digit model’s training data, evaluation conditions or measured accuracy, so its parameter count should not be read as evidence of how well it recognizes handwriting. The source also gives no detailed methodology for the reported language-model score change, including the test setup or how broadly the result applies.
The MIT CSAIL result is described as a blog post with public logs rather than a peer-reviewed paper. The source does not establish whether the reported score improvement was independently replicated, or whether the weight edit affected other capabilities. Those points remain open based on the material provided.
What Further Evidence Would Show
The source does not announce a scheduled follow-up or publication date. The immediate next step for readers is to inspect the linked explainer and, for the separate weight-editing claim, the public logs it references. Further evidence would need to document the model, evaluation method and results in enough detail for others to test whether the reported change holds beyond that example.
For the handwritten-seven demonstration itself, the article’s method is reproducible in principle: follow the input values through each layer’s weights, biases and activations, then compare the output scores. The source does not provide a specific model checkpoint or a new accuracy evaluation, so it explains the computation rather than reporting a newly measured recognition result.
Key Questions
How does the network turn a handwritten seven into an answer?
In the example, a 28-by-28 image becomes 784 pixel values. Hidden layers transform those inputs using weights, biases and activation functions; the output layer returns scores for possible digits.
What does changing the XOR network’s bias do?
Changing the output bias from −2 to −1 makes the demonstrated network return one for all four two-bit inputs, instead of returning one only when the inputs differ.
What are weights and biases?
Weights set how much inputs count in a neuron’s calculation. A bias shifts the neuron’s total before an activation function converts it into an output.
Is the reported AI weight-editing result peer reviewed?
The source describes it as a blog post with public logs, not a peer-reviewed paper. It reports a change in a math score but does not provide enough detail here to establish independent replication or broader effects.
Source: ThorstenMeyerAI.com