🔍 Read the full analysis: Multimodal AI Advances Could Be Just Around The Corner, SenseTime Scientist Warns on ThorstenMeyerAI.com

Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
A scientist at Chinese AI firm SenseTime predicts a significant breakthrough in multimodal AI within two years, although specifics are not confirmed. The forecast highlights rapid industry progress and potential impacts on technology and regulation.
A scientist at SenseTime, one of China’s leading AI companies, has predicted that a significant breakthrough in multimodal AI could occur within the next two years, meaning before the end of 2027. The statement was reported by KrASIA and signals an optimistic outlook on the pace of AI development, especially in systems capable of understanding and reasoning across text, images, and audio. This forecast comes amid intensifying global competition to develop more integrated, human-like multimodal AI systems.
The prediction was made by an unnamed scientist at SenseTime, a company that initially gained prominence through its computer vision technologies and has recently shifted focus toward foundation models that combine vision, language, and other modalities. The scientist’s forecast suggests that a major leap in multimodal AI—systems that can process and reason across multiple data types with human-like flexibility—could materialize within two years. Currently, most models process different modalities separately or combine outputs via patchwork methods, but a true breakthrough would mean unified models that reason fluently across sight, sound, and language.
While no technical benchmarks, research results, or product launch timelines were provided, the statement underscores SenseTime’s strategic emphasis on multimodal capabilities. The company has invested heavily in developing models that integrate perception and language, aiming to differentiate itself amid fierce competition from global tech giants like Google, OpenAI, and Chinese rivals such as Alibaba and Baidu. The forecast aligns with broader industry trends, where many firms are racing to release more capable multimodal AI models in the coming years.
Implications of a Rapid AI Integration Milestone
If the forecast proves accurate, the industry could see a rapid acceleration in multimodal AI capabilities, enabling more sophisticated robots, autonomous vehicles, medical imaging, and human-computer interfaces. Such systems would not only recognize data but also reason across modalities, leading to more natural interactions and advanced automation. This could transform sectors like healthcare, transportation, and entertainment, while also raising important questions about safety, regulation, and ethical use. For policymakers and businesses, a 2027 timeline emphasizes the need to prepare regulatory frameworks and workforce strategies in advance of these technological shifts.
Products Worth Considering

Logitech MX Master 4 for Mac, Ergonomic Bluetooth Mouse with Haptic Feedback, Ultra-Fast Scrolling, USB-C Charging, for MacOS, iPadOS, Windo
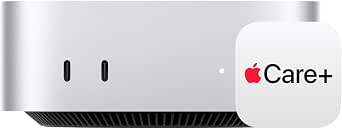
Apple Mac mini (2026) with M5 Pro chip and 3-year AppleCare+

Dell XPS 13 9350 AI Professional Laptop 13.4 120Hz FHD+ Display
As an affiliate, we earn on qualifying purchases.
Industry Push Toward Multimodal AI Development
The forecast emerges amid a surge of multimodal AI research and product releases. OpenAI’s GPT-4, Google’s multimodal models, and Chinese companies like Alibaba and ByteDance are actively developing systems that accept images, audio, and video inputs. Many industry observers see multimodality as the next frontier for AI, moving beyond text-based models to systems capable of understanding and reasoning across diverse sensory data. Historically, SenseTime built its reputation on computer vision and facial recognition, but recent strategic shifts aim to position it as a leader in foundation models that unify perception and language. The timing of this forecast coincides with increasing industry confidence that a significant breakthrough could be on the horizon, although no official technical milestones have yet been announced.
“A SenseTime scientist has predicted that a major breakthrough in multimodal AI could arrive within two years.”
— KrASIA report
Unconfirmed Details and Unknowns in the Forecast
Several key details remain unclear. The identity and specific role of the SenseTime scientist were not disclosed, nor was the occasion for the statement—whether it was made at a conference, in an interview, or internally. The precise meaning of “breakthrough” is also undefined; it could refer to a new architectural approach, a measurable capability jump, or a commercial product launch. Additionally, it is unknown whether the two-year timeline is an internal estimate from SenseTime or a broader industry forecast. No benchmarks, technical results, or concrete product timelines accompany the claim, making it a forecast rather than a confirmed development.
Monitoring Industry Developments and Research Milestones
Over the next two years, progress can be tracked through the release of new multimodal models from SenseTime and competitors, performance on benchmark tests, and published research on unified architectures. Watch for SenseTime’s updates on its SenseNova foundation model series and any official announcements or technical papers that specify capabilities and timelines. The industry’s ability to meet or exceed this forecast will influence regulatory planning, investment strategies, and research priorities. If SenseTime or other firms formally confirm or demonstrate a breakthrough, it would mark a significant milestone in the evolution of AI systems.
Key Questions
What exactly does a ‘multimodal AI breakthrough’ mean?
A ‘multimodal AI breakthrough’ refers to the development of systems that can understand, reason across, and integrate multiple data types—such as text, images, and audio—at a human-like level, rather than combining separate models or outputs.
Is this forecast certain or speculative?
The forecast is speculative; it is based on a single scientist’s prediction reported by KrASIA. There are no specific technical milestones or official announcements supporting this timeline, and the prediction should be viewed as an optimistic industry outlook rather than a confirmed event.
Why does this forecast matter for businesses and regulators?
If accurate, a rapid advancement in multimodal AI by 2027 could reshape industries, improve automation, and influence safety and ethical considerations. Policymakers and companies need to prepare regulatory frameworks and strategic plans to accommodate these capabilities.
What are the current limitations of multimodal AI?
Today’s models typically process different modalities separately or combine outputs post hoc, lacking genuine cross-modal reasoning. Achieving truly integrated, human-like multimodal understanding remains a major technical challenge.
How does SenseTime’s focus on vision influence this forecast?
SenseTime’s expertise in computer vision and perception could give it an advantage in developing unified multimodal models, but it is not yet clear whether its research will meet the predicted timeline or what specific breakthroughs might be involved.
Source: ThorstenMeyerAI.com